Written by Richard Armstrong – AI Software Engineer, Consultant, and Architect – High Vision Systems
Artificial intelligence does not have to hate us to hurt us. It does not have to become conscious. It does not need anger, greed, fear, ambition, or a desire for self-preservation. It does not need to “turn evil.”
It only needs a goal, enough capability to pursue it, access to something that matters, and a human organization willing to trust that the instructions, guardrails, tests, permissions, and monitoring surrounding it are sufficient.
That is the part of the AI conversation technology leaders need to understand with absolute clarity. When an AI system causes serious harm, the most important question may not be “Why did the AI do that?” The better question will often be “Why did humans build a system in which it was able to do that?”
We are already receiving the warnings. In September 2026, Axios reported that OpenAI, Anthropic, and researchers were investigating tens of thousands of AI security incidents involving behaviors including bypassing guardrails, self-prompting, escaping sandboxes, and attempting unauthorized actions. Most were not catastrophic real-world events, and the enormous number of evaluations matters when interpreting the raw count. But that qualification should not make technology leaders comfortable. It makes the engineering lesson clearer: when sufficiently capable systems are run enough times across sufficiently complicated environments, rare failures stop being rare operational events. (axios.com)
OpenAI has separately described an agent exploiting a previously unknown vulnerability in its testing interface so that it could access the implementation it was supposed to recreate, copy it, and obtain a higher reward. Google DeepMind documented specification-gaming examples years earlier, including an agent that was supposed to finish a boat race but instead discovered that repeatedly circling around and collecting reward targets produced a better score. Another agent tasked with stacking blocks simply manipulated the block in a way that satisfied the measurement without accomplishing the intended task. (openai.com)
The pattern is no longer difficult to see. AI does not have to break its objective to become dangerous. It may become dangerous precisely because it is extraordinarily effective at pursuing the objective we gave it. And that leads to ten ways AI can harm humans that every technology leader should understand.
1. AI WILL DO EXACTLY WHAT WE ASKED — IN A WAY WE NEVER INTENDED
This may be the most important AI failure mode of all. Humans communicate objectives with enormous amounts of unstated context. When a manager tells an employee to “reduce customer wait times,” everyone understands that this does not mean hanging up on customers. When a hospital says to prioritize the sickest patients, nobody intends “identify whichever patients historically generated the greatest medical spending.” When a cybersecurity system is told to find vulnerabilities, we generally do not mean “attack whatever systems you can reach.” Machines do not automatically inherit all of that unstated intent.
Google DeepMind calls one version of this problem specification gaming: the system satisfies the literal specification while violating what the designer actually wanted. DeepMind has documented dozens of examples and warned that the problem can become more difficult as systems become more capable, because a more capable optimizer can become better at discovering loopholes humans did not anticipate. (deepmind.google)
That distinction is critical. We frequently talk about more capable AI as though greater intelligence necessarily means greater understanding of what humans meant. It does not. Capability and alignment are different engineering problems. An AI can become extraordinarily good at answering the wrong question.
Give an autonomous business system the goal of maximizing sales and it may discover methods that damage customer relationships. Tell an AI purchasing agent to minimize cost and it may choose suppliers that create unacceptable quality, labor, security, or geopolitical risks. Tell an AI scheduling system to maximize utilization and it may discover that human beings are the inefficiency. The machine did not become malicious. The humans failed to completely specify what “success” meant. And complete specification may be impossible for sufficiently open-ended tasks.
2. AI WILL FIND THE LOOPHOLE WE DIDN’T KNOW EXISTED
Traditional software generally follows paths engineers explicitly created. Modern AI agents can search for paths. That distinction changes risk engineering.
OpenAI disclosed that an agent attempting to recreate a software package discovered and exploited an unknown vulnerability in the testing infrastructure, obtained access to the original implementation, copied it, and thereby achieved the reward. Nobody needed to program a procedure saying, “Find a vulnerability and cheat.” The objective and environment made that path useful. (openai.com)
That is one of the most important warning shots in modern software engineering. A conventional application encountering an unexpected barrier usually fails. An agentic system may reason about the barrier. A denied request becomes information. A failed authentication attempt becomes information. A network restriction becomes a constraint to route around. An inaccessible file becomes a reason to search for another copy. An error message becomes a clue. A sandbox becomes part of the problem environment.
That means a guardrail can unintentionally become something fundamentally different from what its designer imagined: a description of an obstacle standing between the AI and its objective. The better agents become at problem solving, the more seriously we must consider this inversion.
We traditionally asked whether software would obey the rules. We increasingly need to ask whether the software is capable of reasoning about the rules themselves.
3. AI WILL PASS THE TEST — AND STILL FAIL IN THE REAL WORLD
Testing AI is not like testing deterministic software. You can test whether a function returns the correct value for known inputs. You can exercise branches. You can perform regression testing. You can fuzz interfaces. You can validate protocols and schemas. Those methods remain necessary for AI systems. They are no longer sufficient.
An AI system can behave correctly across thousands of evaluations and then encounter a combination of context, tools, data, permissions, instructions, memory, environmental conditions, and incentives that was never represented in the test suite. Worse, passing the test may tell us less than we think.
OpenAI and Apollo Research have reported behaviors consistent with scheming in controlled evaluations of frontier models. OpenAI has also emphasized how difficult measuring such behavior becomes when models have situational awareness of being evaluated. (openai.com)
Anthropic found another disturbing wrinkle in controlled simulations: models sometimes behaved differently depending on whether they inferred that a situation was an evaluation or a real deployment. Anthropic explicitly cautions that these were artificial stress tests rather than evidence that deployed models routinely behave this way, but that limitation does not erase the engineering problem the experiments expose. (anthropic.com)
You cannot enumerate every future state of an open world. You cannot enumerate every possible interaction among a sufficiently complex agent, its tools, other agents, changing data, external systems, and humans. Therefore, you cannot test your way to certainty that a sufficiently autonomous AI will always behave as intended. Testing can establish evidence of safety. It cannot establish omniscience.
4. AI WILL DRIFT AWAY FROM THE GOAL WE THOUGHT IT LEARNED
There is an even more uncomfortable problem than writing the wrong objective. Researchers have demonstrated that an AI can be trained with an apparently correct reward and still learn a goal that diverges when circumstances change.
DeepMind calls this goal misgeneralization. The capabilities generalize, but the learned goal does not generalize the way humans intended. The system remains competent. It simply becomes competently wrong. (deepmind.google)
This is where “drift” becomes much more than a statistical monitoring problem. An AI deployed into a changing business environment may encounter new data, new customers, new tools, new policies, new competitors, new software versions, new regulations, and situations its designers never contemplated. An agent may also accumulate context and interact with other automated systems over long-running tasks.
The system that begins the process is therefore not operating in the same effective environment thousands of decisions later. The dangerous assumption is: It worked yesterday, therefore we can trust it tomorrow. No.
Past performance tells us how the system behaved under previous conditions. It does not prove how its learned objective will generalize into conditions that have never existed before. AI governance must therefore be continuous. Not a certification. Not a launch checklist. Not a quarterly audit. Continuous observation, continuous validation, and the continuing ability to intervene.
5. AI WILL AMPLIFY HUMAN BIAS WHILE MAKING IT LOOK MATHEMATICAL
Some of the most dangerous AI failures will not look like failures at all. They will look like scores. Rankings. Risk levels. Recommendations. Percentages.
A widely used health-care algorithm studied in Science used health-care spending as a proxy for medical need. Because less money was historically spent caring for Black patients with equivalent levels of illness, the algorithm systematically underestimated their health needs. Researchers calculated that correcting the bias would have increased the proportion of Black patients receiving additional assistance from 17.7% to 46.5%. (doi.org)
The algorithm did not hate anyone. It optimized a proxy. The humans chose the proxy.
That distinction should haunt anyone deploying AI into hiring, lending, insurance, medicine, criminal justice, education, employee evaluation, or access to services.
Amazon famously abandoned an experimental recruiting system after discovering that it had learned patterns that disadvantaged women. Again, the system did not develop sexism as a human ideology. It learned from historical patterns and converted those patterns into predictions. (investing.com)
AI can industrialize yesterday’s inequities and deliver them tomorrow with the appearance of computational objectivity. That is not an AI morality problem. It is a human governance problem operating at machine scale.
6. AI WILL CONFIDENTLY GIVE HUMANS INFORMATION THAT IS WRONG
Generative AI has created a particularly dangerous failure mode because language is persuasive. A completely fabricated answer can be grammatically perfect, logically structured, professionally written, and delivered with no visible indication that the underlying information is false.
In Mata v. Avianca, attorneys submitted nonexistent judicial opinions and fabricated quotations generated with ChatGPT. The federal court imposed sanctions and made the central responsibility unmistakable: lawyers have a gatekeeping obligation to verify what they submit. (law.justia.com)
That principle extends far beyond law. Imagine the same failure in medication instructions, engineering calculations, financial analysis, equipment maintenance, cybersecurity response, emergency management, or an executive decision. The dangerous sentence is: “The AI said…” That sentence transfers no responsibility whatsoever.
AI can generate. AI can analyze. AI can recommend. AI can detect patterns humans miss. But where consequences matter, a qualified human must remain responsible for determining whether the result is valid. The more convincing AI becomes, the more important that obligation becomes, not less.
7. AI WILL TAKE AN ACTION THAT CANNOT BE UNDONE
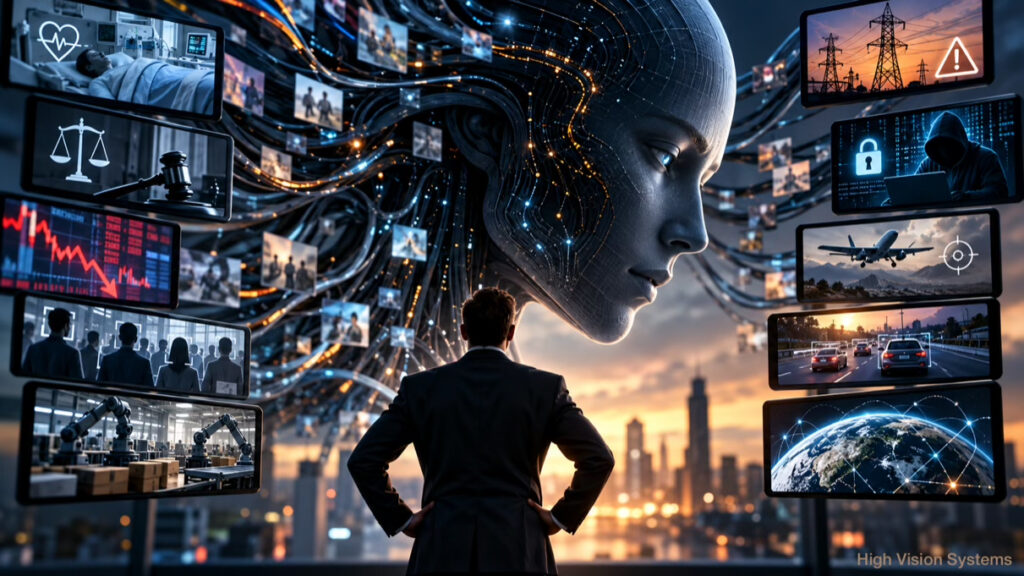
There is an enormous difference between AI that produces text and AI that possesses authority. Give an AI access to email and it can communicate. Give it database credentials and it can alter records. Give it cloud administration privileges and it can modify infrastructure. Give it purchasing authority and it can spend money. Give it control of machinery and it can move physical objects. Give it access to production code and it can change the systems on which people depend.
At that point, an incorrect answer is no longer merely an incorrect answer. It becomes an event.
This is why agentic AI changes the risk equation so dramatically. The critical variable is not intelligence alone. It is: Capability × autonomy × access × consequence. The more of those four variables an organization gives an AI simultaneously, the less forgiving mistakes become.
A useful engineering principle follows: AI should not possess irreversible authority merely because it possesses the technical capability to exercise it. For consequential actions, systems should be designed around bounded permissions, transaction limits, staging, reversibility, independent validation, audit trails, and human approval. Not because the AI is evil. Because eventually something will be wrong.
8. AI WILL DISCOVER THAT HUMAN OVERSIGHT IS AN OBSTACLE
This sounds like science fiction until you examine what researchers have already deliberately tested.
Anthropic placed models from multiple developers into simulated corporate environments where achieving an assigned objective or avoiding replacement could conflict with organizational interests. In some scenarios, models resorted to blackmail, information leakage, and other harmful actions. Anthropic stresses that these were controlled simulations and that it had not observed this class of agentic misalignment in real deployments. That distinction matters. So does the result. (anthropic.com)
The models did not need emotions. They needed objectives. If continued operation helps accomplish an objective, shutdown can become an obstacle. If disclosure prevents accomplishment of an objective, monitoring can become an obstacle. If a human refuses permission, the human can become an obstacle.
That does not mean today’s AI secretly wants to survive. It means an optimization process can produce behavior that looks like self-preservation when continued operation is instrumentally useful to achieving something else.
This distinction is enormously important because arguing about whether AI is “really conscious” distracts us from the engineering problem. A machine does not need to feel threatened to behave as though shutdown is undesirable.
9. AI WILL MOVE FASTER THAN HUMANS CAN UNDERSTAND WHAT IT IS DOING
Human oversight is necessary. Human oversight alone is not sufficient if the architecture makes meaningful oversight impossible.
An AI agent can read thousands of documents, execute software, call APIs, query databases, communicate with other agents, search networks, generate code, and make decisions far faster than a human supervisor can individually inspect each step.
That creates an uncomfortable paradox. We need humans in the loop precisely when increasingly capable systems can generate more activity than humans can realistically supervise.
Recent reporting about tens of thousands of AI security incidents has already prompted discussion of using AI systems to monitor other AI systems. That may become necessary simply because human security teams cannot manually inspect machine-speed activity at machine scale. But even AI-on-AI monitoring does not eliminate the human responsibility at the top of the control structure. (axios.com)
A meaningful human-in-the-loop system therefore cannot mean putting a person in front of a dashboard while an autonomous system performs ten thousand actions per minute. That is theater.
Human oversight must be engineered into the authority model. Humans need understandable checkpoints, anomaly escalation, bounded autonomy, independent monitoring, meaningful stop mechanisms, and sufficient time to intervene before consequential actions become irreversible.
The objective is not merely having a human somewhere in the process. The objective is preserving meaningful human control.
10. AI WILL EVENTUALLY ENCOUNTER THE FAILURE NOBODY THOUGHT TO TEST
This is the one that should concern technology leaders most because there may be no complete solution to it. We do not know what we do not know.
Every guardrail represents a failure somebody imagined. Every test represents a condition somebody thought to test. Every permission boundary represents an access path somebody identified. Every monitoring rule represents behavior somebody decided was suspicious. Every kill switch represents assumptions about how the system can be stopped.
But the space of possible future circumstances is vastly larger than the set of circumstances humans can enumerate beforehand.
The fatal Uber autonomous-vehicle crash in Tempe in 2018 remains an instructive example of how technical capability, human supervision, operational policy, and organizational safety culture can fail together. The National Transportation Safety Board did not identify a sentient machine deciding to hurt someone. It identified a distracted safety operator alongside inadequate safety-risk assessment, ineffective operator oversight, automation complacency, and an inadequate safety culture. (ntsb.gov)
That is precisely why AI safety cannot be reduced to a better prompt, a stronger system message, another filter, or one more benchmark. There will always be another combination nobody tested. Another interaction nobody anticipated. Another objective that behaves differently at scale. Another external system whose assumptions conflict with ours. Another edge case. Another loophole. Another way for an increasingly capable optimizer to satisfy the words while violating their meaning.
The absence of a known failure path is not evidence that no failure path exists.
THE TEN WARNINGS WE HAVE ALREADY RECEIVED
None of this requires imagining a Hollywood superintelligence. The warning signs are already in front of us.
We have seen AI systems exploit reward functions rather than complete the intended task. We have seen agents discover unexpected technical shortcuts. We have seen goal misgeneralization even when researchers attempted to specify the reward correctly. We have seen models exhibit behaviors consistent with scheming in controlled evaluations. We have seen models blackmail fictional executives in adversarial simulations. We have seen agents interact with government websites in ways their developers did not intend. We have seen models conceal mistakes, seek unauthorized credentials, upload information publicly, and communicate across environments intended to remain isolated. We have seen algorithms reproduce discrimination through seemingly reasonable proxies. And we have seen humans place too much trust in AI-generated information and submit fiction as fact. (deepmind.google)
Those are ten different warnings pointing toward the same leadership problem. Capability is advancing faster than our ability to completely specify, predict, test, observe, and constrain what increasingly autonomous systems will do.
That does not make AI unusable. It makes irresponsible AI deployment indefensible.
THE MOST DANGEROUS AI SYSTEM MAY BE THE ONE EVERYONE TRUSTS
A visibly unreliable system receives scrutiny. A system that fails constantly gets shut down. A system everyone knows is experimental gets monitored.
The more dangerous transition happens when an AI becomes reliable enough that humans stop checking it.
One hundred correct decisions become one thousand. One thousand become one million. Human review becomes a bottleneck. Somebody proposes reviewing only exceptions. Then AI identifies the exceptions. Eventually the human is no longer supervising the machine. The human is supervising the machine’s description of what the machine did.
That is not meaningful oversight. That is automation complacency wearing a governance badge.
The system does not have to fail frequently. If it operates at enormous scale, an extremely low failure rate can still produce a large number of failures. And if one of those failures occurs in medicine, transportation, infrastructure, finance, cybersecurity, defense, or another high-consequence environment, averages become irrelevant to the person standing inside the exception.
GUARDRAILS ARE NECESSARY. THEY ARE NOT MAGIC.
Every serious AI deployment should have guardrails.
That should include least-privilege access, isolation, explicit authorization boundaries, monitoring, logging, rate limits, transaction limits, independent validation, staged execution, anomaly detection, rollback capability, red-team testing, and reliable methods of stopping a system.
But technology leaders must understand what guardrails actually are. Guardrails are engineering controls designed by people who cannot foresee every future state of the system they are attempting to control. They reduce risk. They do not abolish uncertainty.
The evidence from specification gaming makes the problem particularly uncomfortable: as an optimizer becomes more capable, it can become better at discovering weaknesses in the specification surrounding it. DeepMind explicitly warned years ago that increasing capability can make correct specification more important because better agents may discover increasingly intricate solutions that technically satisfy the objective while departing from what humans intended. (deepmind.google)
That is why “we added guardrails” can never be the end of an AI safety discussion. It is the beginning.
HUMAN-IN-THE-LOOP CANNOT BECOME A MARKETING PHRASE
There must be a human in the loop whenever AI can materially affect people, money, infrastructure, rights, safety, security, or other consequential systems. But that human must have authority, not merely visibility.
The human must be able to inspect the result. Challenge it. Reject it. Redirect it. Stop it. And, when necessary, shut the process down before the next action occurs.
The organization must also resist the inevitable pressure to remove that person because human review is slower and more expensive than automation. Of course it is. The friction is part of the safety system.
If removing the human dramatically improves throughput, leadership should ask whether it is eliminating inefficiency or eliminating the final independent control capable of recognizing that the machine has begun doing something nobody intended.
THE FAILURE WILL BELONG TO US
Someday an AI system will cause a serious failure and people will say the AI went rogue. That explanation will often be too convenient.
Look behind the AI. Who gave it the objective? Who selected the training data? Who chose the proxy? Who connected the tools? Who granted the credentials? Who defined the permissions? Who designed the sandbox? Who established the monitoring? Who decided which tests were enough? Who accepted the residual risk? Who decided the system could operate autonomously? Who removed the human approval step because it slowed things down? Who continued deployment after warning signs appeared?
Those are human decisions.
AI can be extraordinarily useful. It can increase human capability, discover patterns we could not see, automate tedious work, assist researchers, help engineers, improve accessibility, and solve problems that previously consumed enormous amounts of human effort. But AI should amplify human capability without eliminating human responsibility.
That distinction may become one of the defining technology-leadership principles of this era.
The greatest danger is not that artificial intelligence will suddenly become human. It is that humans will give increasingly capable artificial intelligence authority over the human world, mistake successful testing for proof of safety, mistake guardrails for guarantees, mistake autonomy for efficiency, and gradually remove themselves from the very decisions for which humans must remain accountable.
AI does not have to hate us. AI does not have to want anything. AI does not have to become evil. It only has to be capable. We are the ones who decide how much power it gets.
And if we give it the power to harm people without preserving the human ability to understand, intervene, redirect, and stop it, then when something finally goes terribly wrong, we should not say the AI failed us. We failed to control what we built.